A deadlock in operating system terms happens when two or more processes wait for each other forever. Each one holds a resource the other needs, so none of them can continue. The system does not crash, but the affected processes freeze, and sometimes the whole application stops responding.
This guide explains the four conditions that cause deadlock, shows an example, and compares the four ways to handle it: prevention, avoidance, detection and recovery, and simply ignoring it.
A simple example
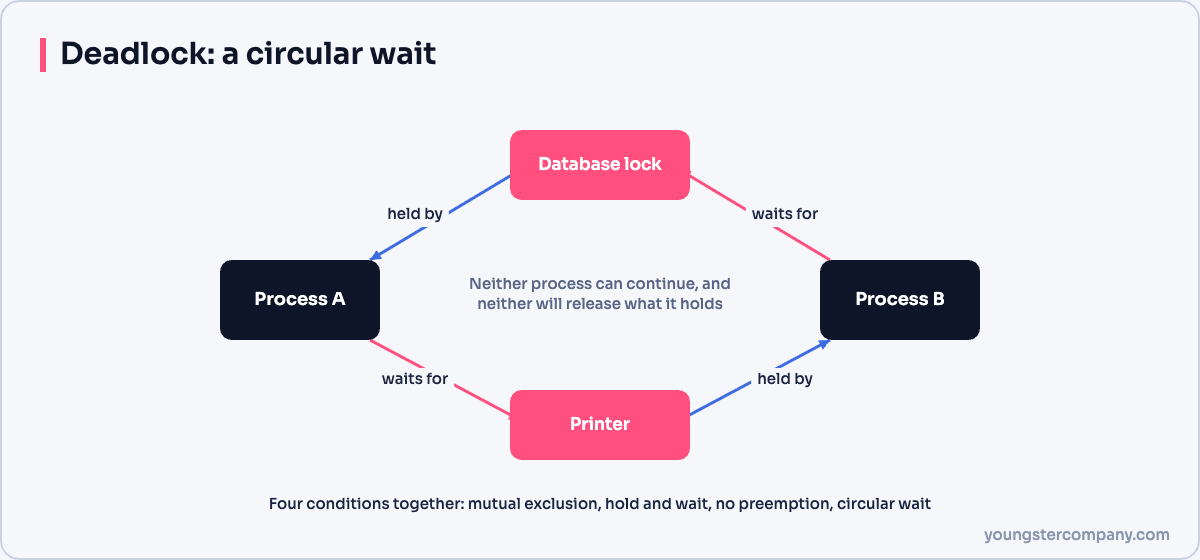
Imagine two processes and two resources, a printer and a file:
- Process A locks the file.
- Process B locks the printer.
- Next, A asks for the printer and waits, because B holds it.
- Then B asks for the file and waits, because A holds it.
Now both wait for each other, and neither will ever release what it holds. The same pattern appears with database rows, mutexes in multithreaded code and network connections.
The four conditions for deadlock
A deadlock can occur only when all four of these conditions, often called the Coffman conditions, hold at the same time:
| Condition | Meaning |
|---|---|
| Mutual exclusion | At least one resource can be used by only one process at a time |
| Hold and wait | A process holds one resource while waiting for another |
| No preemption | The system cannot forcibly take a resource away from a process |
| Circular wait | A closed chain of processes exists, each waiting for the next |
Break any one condition, and deadlock becomes impossible.
Resource allocation graphs
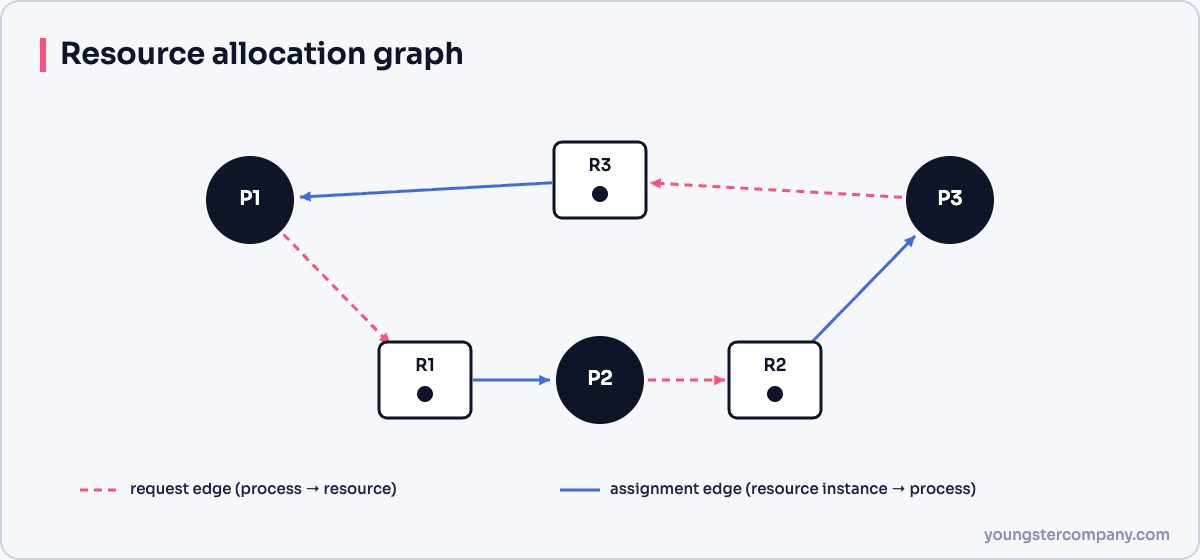
Operating systems often model resources and processes as a graph. Arrows show which process holds which resource, and which resource each process is waiting for. If every resource has a single instance, a cycle in the graph means deadlock. With multiple instances, a cycle means deadlock is possible but not certain.
Method 1: Deadlock prevention
Prevention designs the system so that at least one condition can never hold:
- Mutual exclusion: make resources shareable where possible, for example read-only files. However, many resources, like printers, cannot be shared.
- Hold and wait: require processes to request all resources at once. This works, but it wastes resources and can starve processes.
- No preemption: if a process cannot get a resource, it releases what it holds and tries again later.
- Circular wait: number all resource types and require processes to request them in increasing order. In practice, this is the most common technique, for example when developers always acquire locks in the same order.
Method 2: Deadlock avoidance
Avoidance allows all four conditions but checks each request before granting it. The system grants a request only if it stays in a safe state, where some order exists that lets every process finish.
The classic algorithm is the Banker’s algorithm, proposed by Edsger Dijkstra. Each process declares its maximum needs in advance. Before granting a request, the system simulates the allocation and checks whether a safe sequence still exists. If not, the process waits.
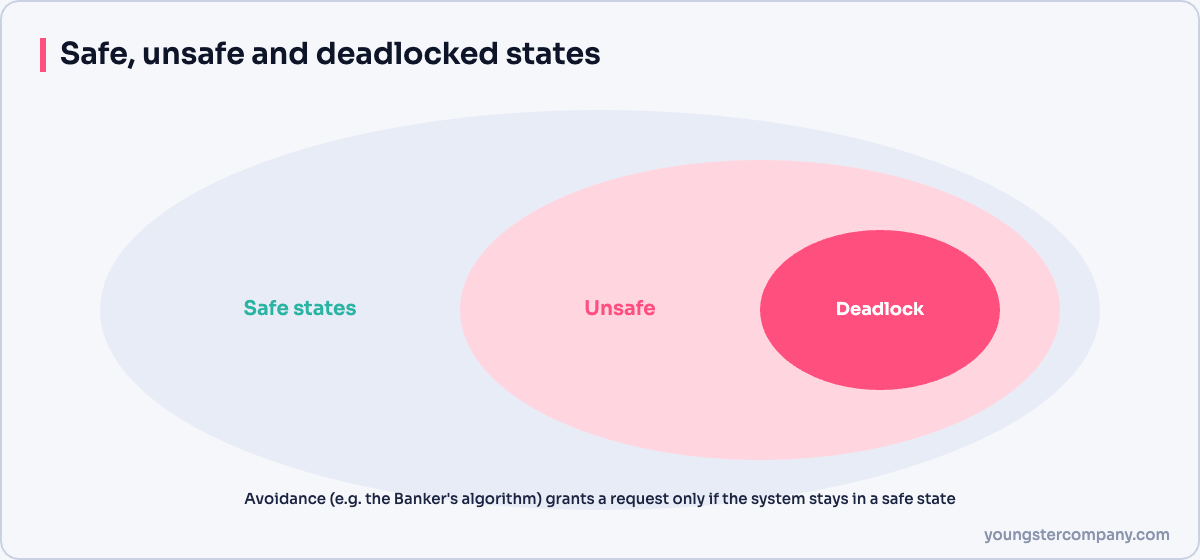
Avoidance is elegant, but it needs advance knowledge of maximum needs, which real systems rarely have.
Method 3: Detection and recovery
Here, the system lets deadlocks happen, detects them and then recovers. Detection runs an algorithm, similar to the Banker’s safety check, at intervals or when CPU usage drops. Once it finds a deadlock, the system can:
- terminate processes, either all deadlocked processes or one at a time until the cycle breaks;
- preempt resources, taking a resource from one process and rolling that process back to a safe checkpoint.
Database systems use this approach. For example, they detect deadlocked transactions and roll back one of them as the “victim”.
Method 4: Ignore the problem
Many general-purpose operating systems, including Linux and Windows, do not prevent deadlocks between user programs. Deadlocks are rare, and the cost of preventing them everywhere would be high. Instead, the responsibility falls to application developers and to tools such as lock-order checkers.
Comparison
| Approach | Pros | Cons |
|---|---|---|
| Prevention | Deadlock can never happen | Lower resource use, possible starvation |
| Avoidance | Flexible and safe | Needs maximum needs in advance; overhead |
| Detection and recovery | High resource use | Lost work when processes roll back |
| Ignore | No overhead | Rare deadlocks need manual fixing |
Related guides
Sources
Running Linux servers in production? Our Linux server hardening & security audit checks configuration, patching, SSH and logging. You can also use our free Linux server hardening checklist, or contact us.